
About This Architecture
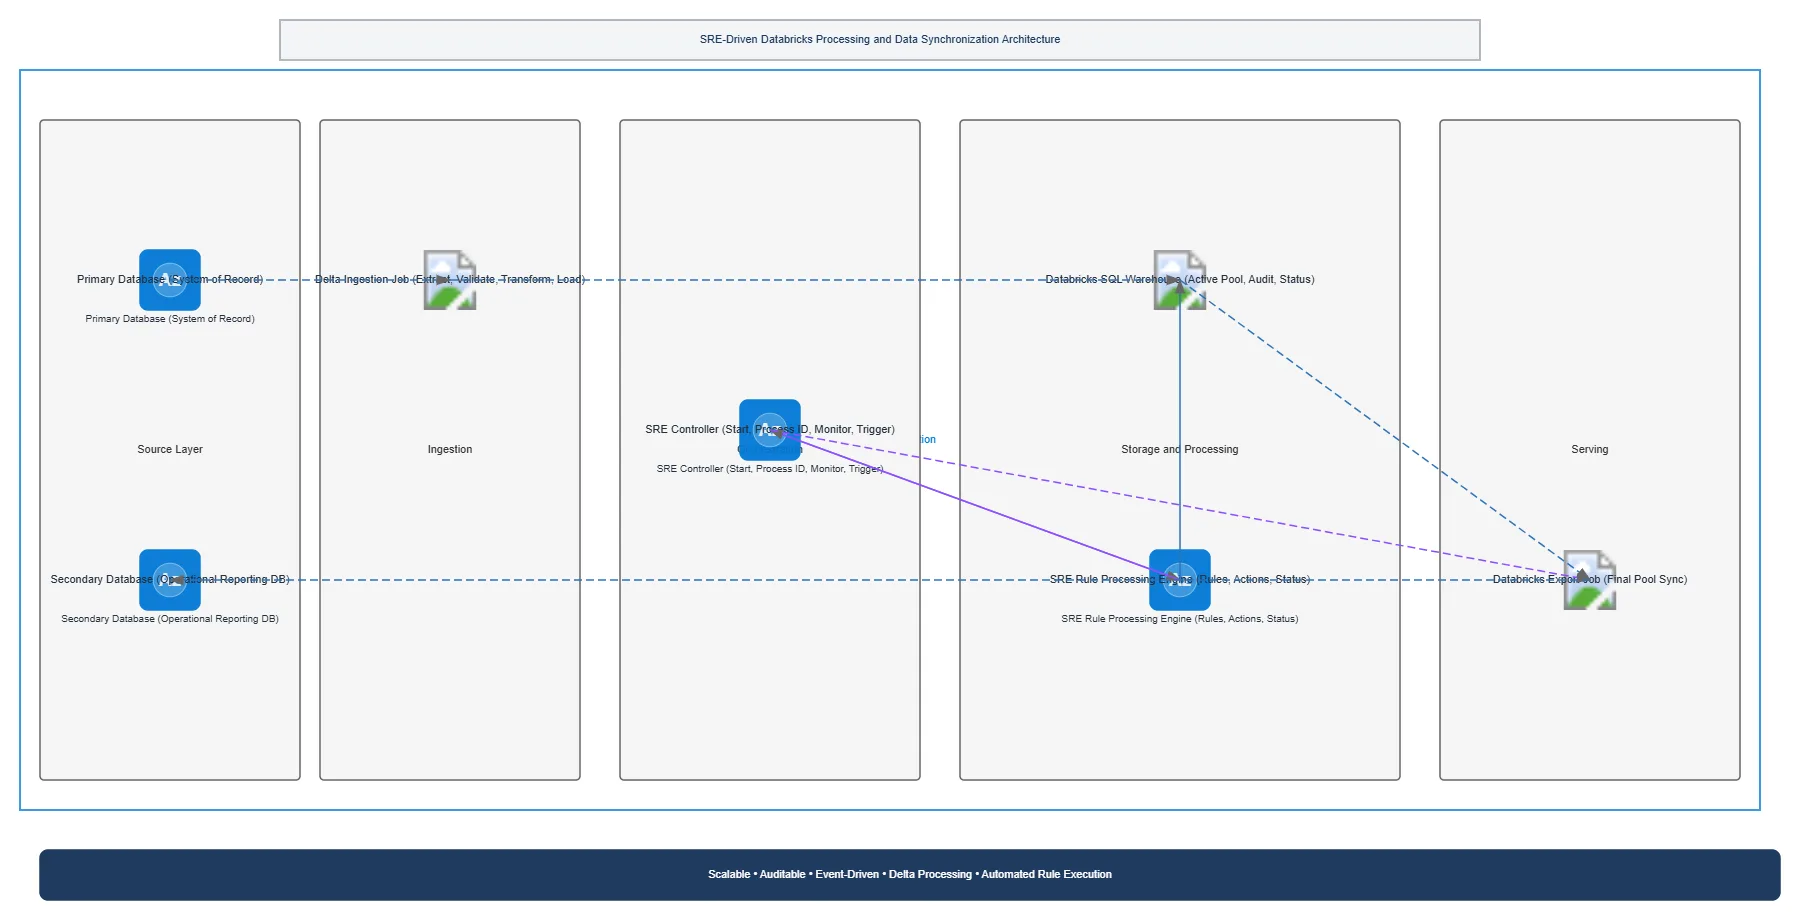
SRE-driven Databricks processing and sync architecture automates data movement from a primary system of record through Delta ingestion, transformation, and rule-based processing into operational reporting databases. The SRE Controller orchestrates the entire flow, triggering Delta Ingestion Jobs that extract, validate, and load data into Databricks SQL Warehouse while the SRE Rule Processing Engine applies business rules and actions to enrich data quality and compliance. Databricks Export Jobs then synchronize processed data to secondary operational databases with full audit trails and status tracking. This event-driven, Delta Lake-based approach enables SREs to build scalable, auditable data pipelines with automated rule execution and comprehensive monitoring. Fork and customize this diagram on Diagrams.so to tailor orchestration logic, rule configurations, and pool sizing to your infrastructure needs.