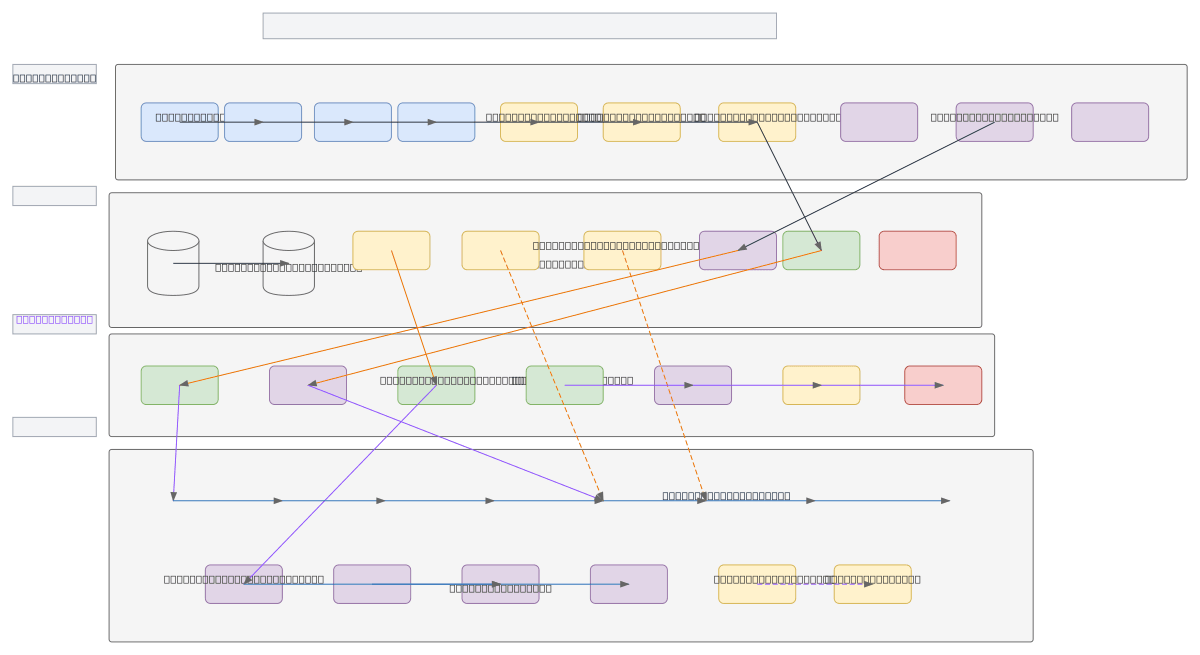
x64 NPU Architecture - AI/ML Inference architecture diagram

About This Architecture

x64 NPU architecture combines quad-core x64 CPU complex with dedicated NPU core array for high-throughput AI/ML inference acceleration. Host CPU manages scheduling and OS runtime while NPU cores execute tensor operations via MAC arrays, quantization engines, and SIMD units, connected through PCIe 5.0, AXI4 NoC, and CXL 2.0 coherency fabric. Memory hierarchy spans DDR5 main memory, HBM2e NPU-local memory, and multi-level SRAM buffers with DMA engine for efficient data movement and ECC protection. This heterogeneous compute design delivers low-latency inference by offloading matrix operations to specialized hardware while maintaining CPU control, addressing the performance and power efficiency demands of edge and datacenter AI workloads. Fork this diagram on Diagrams.so to customize core counts, memory configurations, or interconnect protocols for your specific inference requirements.

People also ask

How does an x64 NPU architecture accelerate AI/ML inference with dedicated tensor cores and memory hierarchy?

x64 NPU architecture separates compute: quad-core x64 CPU handles scheduling and control via CPU Scheduler/OS Runtime, while NPU Core Array executes tensor operations through MAC arrays, quantization engines, and SIMD units. HBM2e NPU-local memory and multi-level SRAM buffers minimize data movement latency, connected via PCIe 5.0, AXI4 NoC, and CXL 2.0 coherency for efficient inference throughput.

x64 NPU Architecture - AI/ML Inference

AutoadvancedNPU architectureAI inferencehardware accelerationtensor processingmemory hierarchyheterogeneous computing
Domain: Ml PipelineAudience: AI/ML hardware architects and systems engineers designing NPU-accelerated inference platforms
34 views0 favoritesPublic

Created by

April 12, 2026

Updated

November 4, 2026 at 4:51 PM

Type

architecture

Make your own

Need a custom architecture diagram?

Describe your architecture in plain English and get a production-ready Draw.io diagram in seconds. Works for AWS, Azure, GCP, Kubernetes, and more.

Generate with AI

AI-generated. Verify before production use. Learn more

Report this diagram